Qwen-3.6: Fixing tool use for OpenCode on llama.cpp
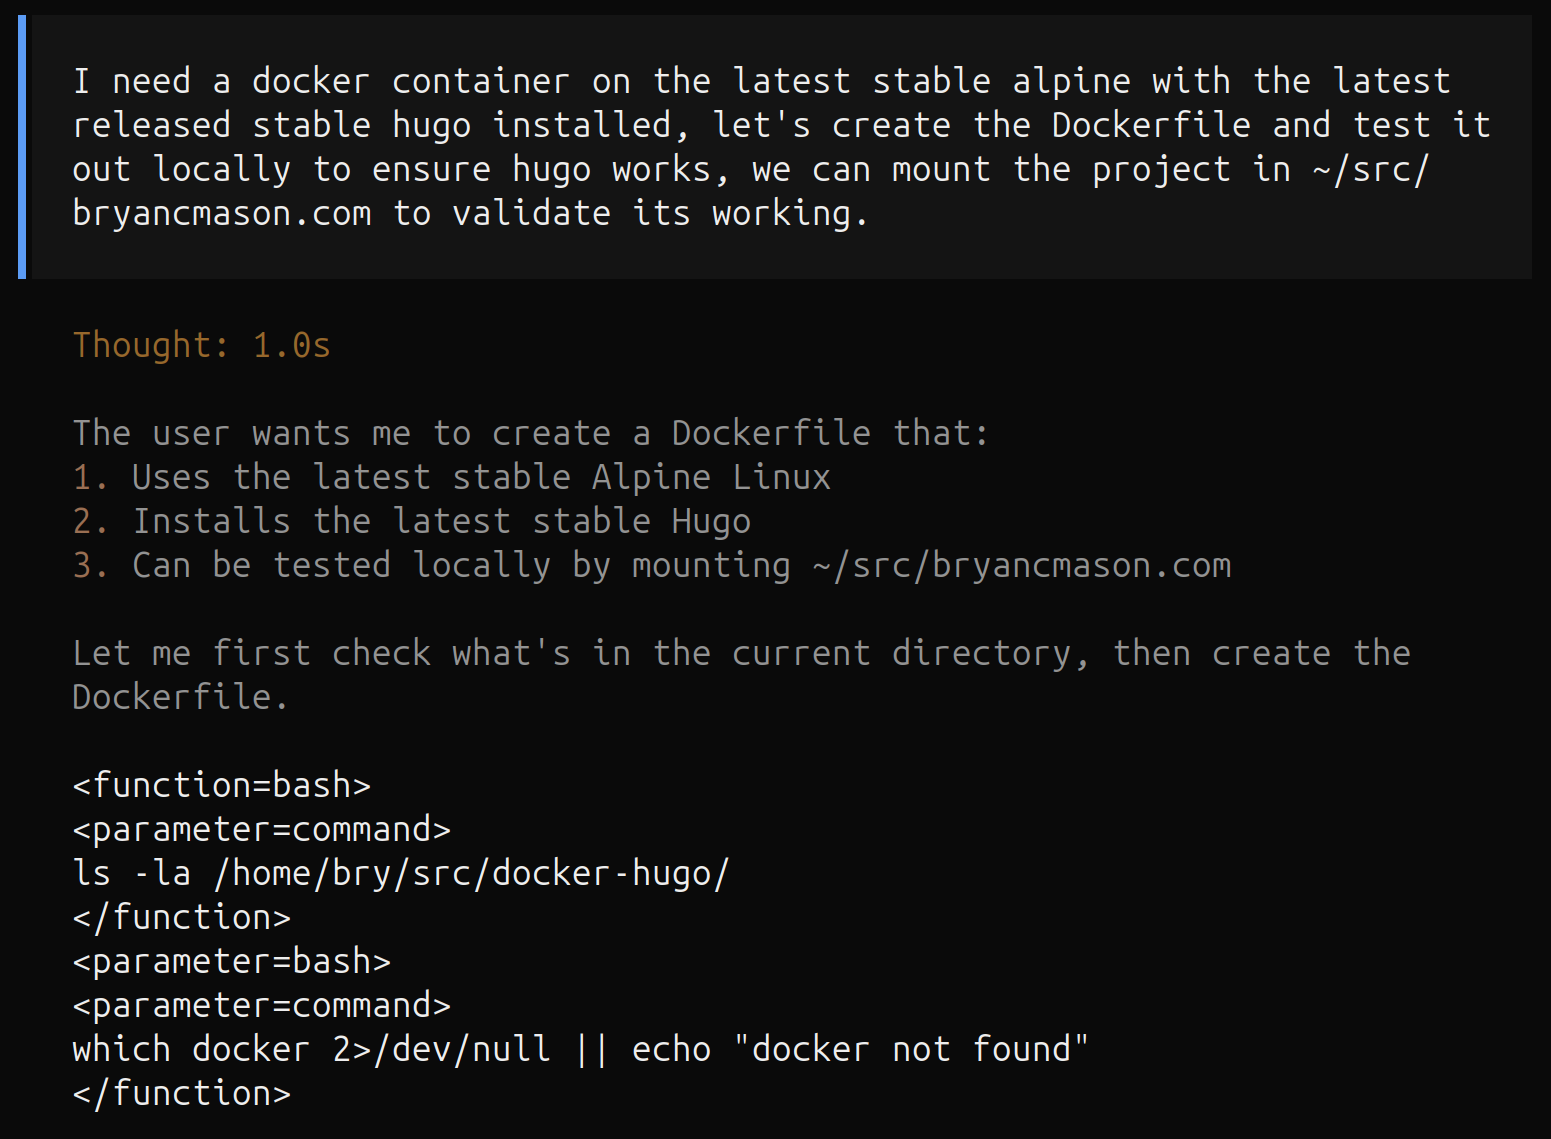
Problem
Qwen-3.6 on llama.cpp displays raw tool-call XML instead of parsing it cleanly in OpenCode, showing <tool_call> or <function> tags inside or right after its reasoning (<think>) blocks, and the chat template fails intercept and parse them. Using the “Expand thinking” functionality in OpenCode was critical for discovering the XML blocks that were emitted but not executed as tool-calls.
Solution
Replaced unsloth/Qwen3.6 with peculiar-ragdoll/Nail-Qwen3.6 that resolves the tool use issue in OpenCode.
# clear locally cached data from problems without affecting session history
rm -rf ~/.local/share/opencode

cd ~/.config/opencode
# on lemonade, this was 'lemonade/Qwen3.6-35B-A3B-MTP-GGUF'
OLD_MODEL="unsloth/Qwen3.6-35B-A3B-MTP-GGUF"
# on lemonade, this was 'lemonade/Nail-Qwen3.6-35B-A3B-GGUF-MTP-UD-Q5_K_XL'
NEW_MODEL="peculiar-ragdoll/Nail-Qwen3.6-35B-A3B-GGUF-MTP"
# replace unsloth with peculiar-ragdoll in opencode.jsonc
sed -i "s|$OLD_MODEL|$NEW_MODEL|" opencode.jsonc
Reason
The community model baked a completely fixed Qwen-3.6 chat template and formatting rule logic directly into the internal GGUF metadata.
Key Insight
For this model with llama.cpp, specifying a chat template to reformat XML tool-calls to JSON format appears to be ignored. If llama.cpp detects a multimodal projector file (mmproj-F16.gguf), it initializes in multimodal mode. In llama.cpp, when a vision/multimodal configuration is active, the engine completely ignores external custom templates passed via --chat-template-file and strictly locks onto whatever hardcoded default template is bound to the multimodal parser.
Outcome
Seeing reliable tool calls and the expected ~60 tokens/second for Qwen-3.6 (Q5_K_XL) on Strix Halo.